

This post, laying out the known facts about destructive scanning of books for AI, ended up being ridiculously long: I broke in into more easily digestible parts:
How AI destroys books and mostly forgets them;
Real-life examples of AI companies buying collectible and scarce books for destructive scanning.
And an additional one, how books are ending up at a toilet paper factory in Mexico.
I also wrote an earlier over-view of AI and book scanning.
*
If you want a really deep dive, here it is:
Over the last couple of weeks, major news outlets (The Washington Post, The Guardian [here and here], the Irish Times, and many others) have picked up on what rare and used booksellers have known for months: Shadowy organizations are ordering large quantities of books with ISBNs for the purpose of cutting them up with machine called a guillotine and scanning them to train AI models.
This interest in printed books springs from a court ruling last summer that scanning a book for AI training complied with American copyright law as long as the original was destroyed in the process. “One replaced the other,” the judge in Bartz v. Anthropic explained.
For my previous Substack post on book scanning, I relied on media reports and court documents. After I hit send, I kept poking around.
At the risk of going all Big Lebowski here, “I’ve got information, man. New shit has come to light.”1
Millions of books are being destroyed to train AI? Nope, it’s tens of millions.
At least the robots are absorbing the contents of the books, so the books that get destroyed live on? Nope, that’s not how large language models (LLMs) work.
AI companies don’t buy rare and collectible books? Nope, they’ve ordered some from me.
Only one copy of each book gets destroyed, so we aren’t losing anything? Nope, thousands of titles are disappearing from the marketplace.
These AI guys can’t be as bad as everyone thinks they are? Nope, AI industry executives are astonishingly cavalier about their book-destroying practices.
Millions of books are being destroyed to train AI? Nope, it’s tens of millions.
News reports have centered on Anthropic’s book scanning because details of its program, called Project Panama, came to light in court filings. The company’s goal was to “destructively scan all the books in the world.” However, it is far from the only company involved. The book scanning ecosystems includes AI developers, book acquisition firms, and scanning companies.
AI Developers
In a statement to The Guardian, Anthropic implied that destructive scanning was standard operating procedure, saying, “sourcing books is a widely used approach for training large language models across the AI industry.”
We should believe them.
In 2024 and 2025, the AI scanning projects mostly happened under the radar. Everyone involved signed NDAs and the companies primarily bought from mega-sellers, like Better World Books, World of Books, and Thrift Books. Individual bookstores, even Powell’s and The Strand, were considered too small.
Eventually, the need for books, particularly specialized titles, outgrew the mega-sellers, and orders began to flow last December through the used book marketplaces, beginning with Alibris before spreading to Biblio.com, Abebooks, and Amazon’s Marketplace.
Meta
It appears that Meta had a book scanning operation running simultaneously with Anthropic’s. Hints about it can be found online. It may have matched Anthropic’s in scale and destructiveness.
Meta acqui-hired the machine translation expert Kenneth Heafield and his team in late 2023. At Meta, Heafield “built physical acquisition” for text-pretraining of the Llama AI models. Physical acquisition sounds a lot like printed books.
The other suggestive evidence of Meta’s book scanning program is that Heafield left the social media company after two years and in weeks launched a book buying and scanning company with the capacity to process 400,000 books per month. Without prior experience at a company the size of Meta, spinning up an operation capable of buying and coordinating the logistics for hundreds of thousands of books would be very difficult. And probably not coincidentally, the scanning contractor used by Heafield’s startup claims to have undertaken “one of the largest scanning projects in history—digitizing millions of books” for “a major social media company.”
SpaceXAI
Elon Musk confirmed that his AI company was scanning physical books when he posted on X, “I’ve asked the SpaceXAI team to preserve any rare books in a library and scan them the hard way vs just cutting off the spine and scanning.” I doubt that Musk’s brief moment of love for books will survive his lawyers. He may have forgotten that destroying books is a requirement to make the scanning legal.
Amazon
Today (August 17), 404 Media reported that it had tracked a book purchased on Biblio to an Amazon warehouse in Las Vegas, and more specifically to a program called VGT3. According to 404 Media, they found a comment by someone on an Amazon worker forum saying VGT3 scans books. What’s curious about this is that Amazon owns both Amazon Marketplace and Abebooks, the two largest online sites for used books.
Book Acquisition Firms
Anthropic is thus just one of four top AI companies with book scanning programs (that we know about). It’s probably safe to assume the others do, too.
Anthropic and Meta seem to have handled book acquisition in-house. Now at least four companies are providing acquisition services for AI: Zoom Books, Far Corner, Last Token, and Innodata. All four of these companies appear to have moved into this line of business in the last year.
Zoom Books
The only company previously identified in the media as supplying books for destructive scanning is Zoom Books, a Canadian mega book “processor”2 similar to Thrift Books.
Earlier this year, the company hired Reed Pannell as its Chief Growth Officer. Pannell’s previous position was director of business development for World of Books, where he was responsible for “spearheading the global [business to business] sales and sourcing strategy.” World of Books, a British company, was one of Anthropic’s key suppliers, and during the two-year heyday of Project Panama its operating profit more than doubled to £21 million.3
With Pannell on board, Zoom Books rushed headlong into large scale book acquisition and a social media firestorm when a Spanish news site ran a story under a headline that translates as “The Mysterious Company that Buys Old Books to Train AI and Then Destroys Them.” Zoom Books denied that it was destroying books, but not that its customers were.

Coincidentally, the PrepFort warehouse in Wood Dale, IL, where many Zoom Books are sent, just happens to need people for “processing high volumes of books.”
Zoom Book orders dried up after the media attention. Most booksellers think they are still operating, but under one or more of the many code names associated with large orders of books. They are also approaching bookstores directly.4 The BBC reported on a bookstore in northern England that received an order from a Canadian company, very likely Zoom Books, the size of which the owner had “never seen the like of.”
Before Zoom Books went quiet,5 Pannell engaged in an online discussion about the company in a Facebook group. One bookseller accused Zoom Books of selling books it didn’t own. While the dealer didn’t use the word, they suggested that Zoom Books was what many in the trade derogatorily call a “bookjacker.” Bookjackers don’t own books, they write software programs to scrape other booksellers’ data, repackage it, and offer the books for sale at higher prices in various corners of the Internet.
Pannell emphatically rejected even the hint of the bookjacker label. “With all due respect,” he wrote, “that is categorically false.” He explained the Zoom Books’s purchases: “We just have a need for these books and are sourcing them via the marketplaces.”
Someone else chimed in to ask the question on every bookseller’s mind, “Will it continue indefinitely?” Pannell responded, “That’s the goal.” He added a smiley-face emoji.
Far Corner
Far Corner is another company buying books in bulk, primarily through Biblio (at least that’s the only site where they use their real name on the orders).
Far Corner is a bookjacker that also provides software designed for bookjackers. They call it “the world of virtual inventory.”
More accurately, Far Corner seems to have scraped listings from other bookstores to augment their own offerings. Or at least they did until about a month ago.6 Their book website, Superbookdeals, no longer accepts orders, and I could not find their seller account on Amazon. Perhaps they are too busy buying books for destructive scanning to deal with arbitraging used books.
404 Media placed a tracker in a book ordered off of Biblio, which likely means it came through Far Corner. That book ended up at an Amazon warehouse.
The bookseller Lucy Kruesel, of Diatom Books in Minnesota, has received a number of orders from Far Corner. She worried about where some of her books were going, so she contacted Biblio’s CEO, who she knows from her days interning at the company. He assured her that Far Corner was reliable but that he couldn’t say what would happen to the books.
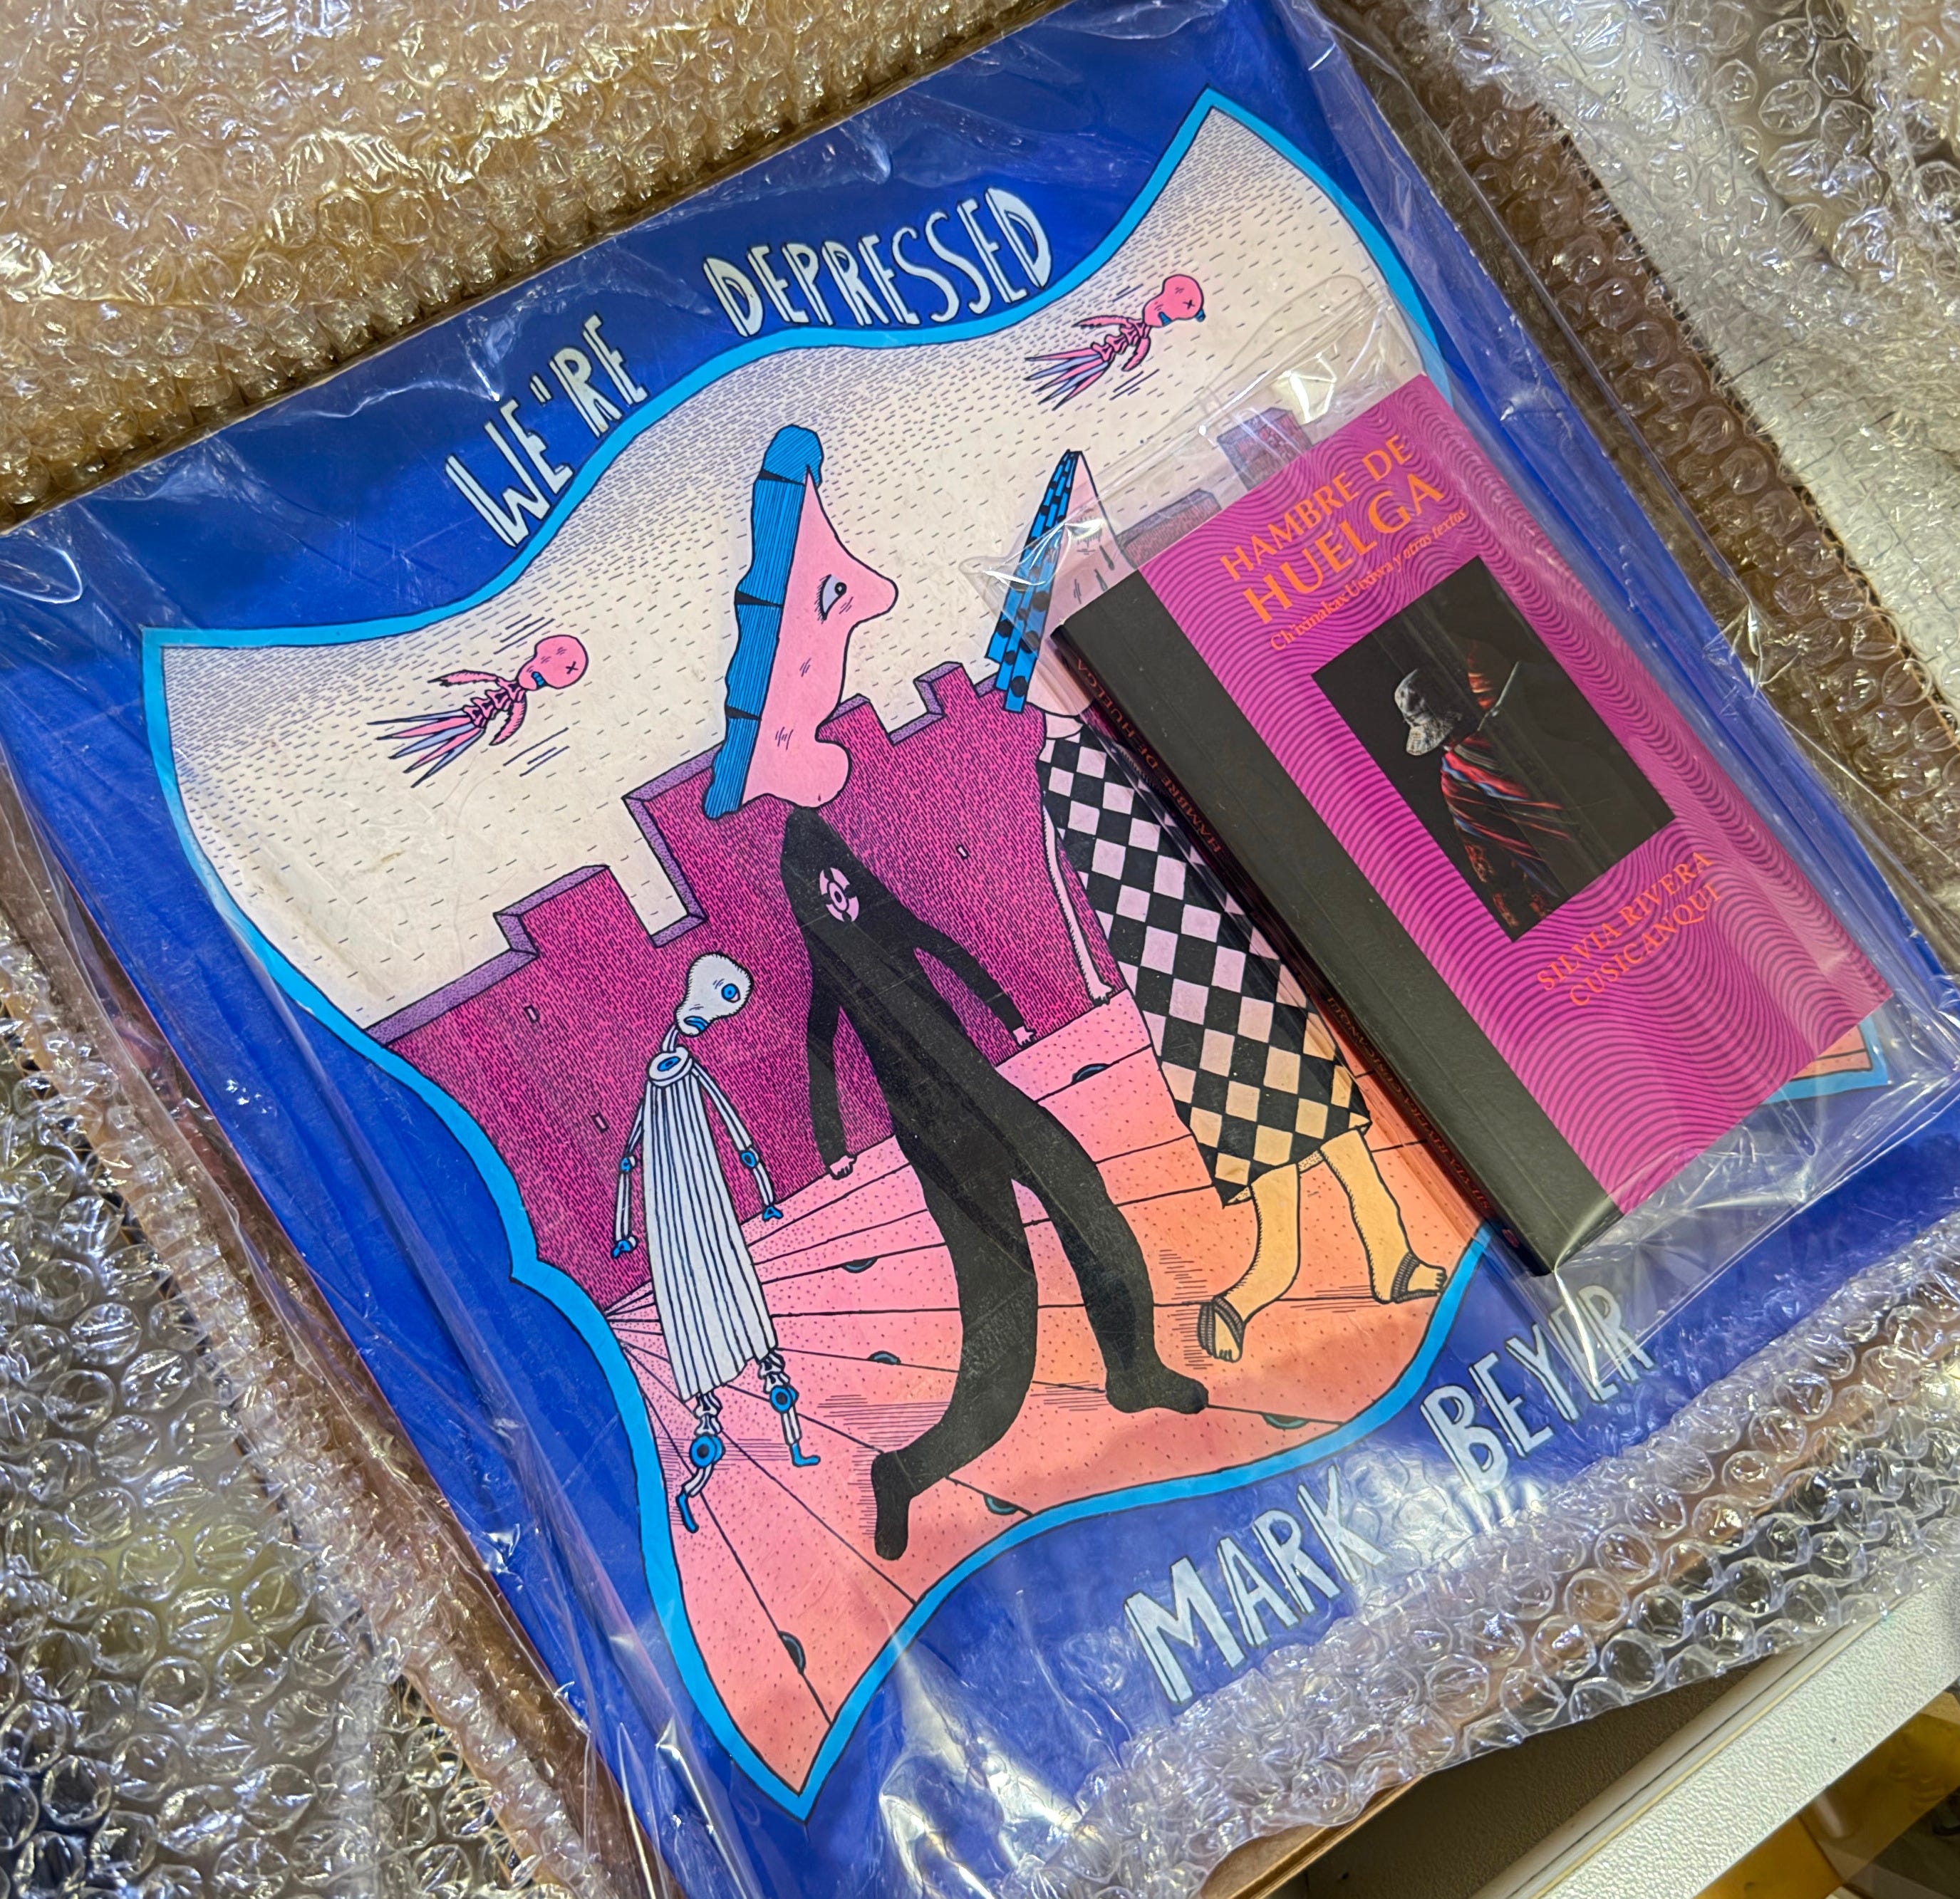
Far Corner bought Kruesel’s copy of Hambre de Huelga: Ch’ixinakax Utxiwa y otros textos by Silvia Rivera Cusicanqui, a small-press Mexican book by an indigenous Bolivian sociologist. In the same box she shipped Mark Beyer’s independently published graphic novel, We’re Depressed. The only thing these two books obviously have in common is that they have ISBNs and they’re obscure. Kruesel had the only copies available online at the time.
Last Token
Last Token is the only startup so far in the book-acquisition field. The other companies pivoted from previous book-related lines of business. Last Token is the business Kenneth Heafield founded after he left Meta. He explained Last Token’s mission on LinkedIn:
First launch product is book scanning. We integrate several metadata sources to help select books and avoid waste, buy books in our marketplace of bulk used and new sellers, ship them to scanning partners, importantly but sadly destroy the books to keep things legal per Bartz v Anthropic, and OCR.
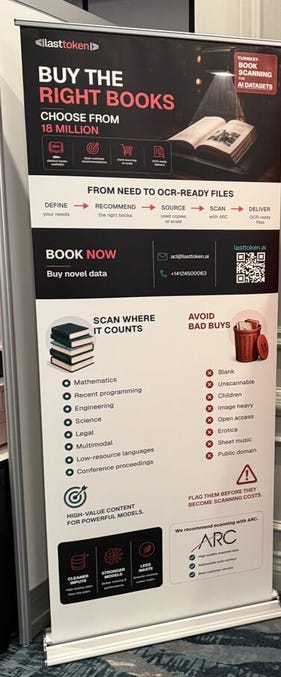
Among the services Last Token offered on a trade show banner was filtering potential book acquisition lists for “bad buys.” Third on the list of bad buys was “children,” which is inarguable. The top item on the list was blank books, which has comic possibilities. What would an LLM make of a blank book with an ISBN that was intended as a joke, like the thirtieth anniversary edition of Dr. Alan Francis’s Everything Men Know About Women?
Last Token is one of several purchasers consolidated under Alibris’s generic “Autobuy” shipping designation, the first source of AI orders to reach used bookstores.7 Heafield’s service is already successful enough that he “paused venture capital because there is customer traction.”
Innodata
Booksellers on Amazon report that Innodata, one of the primary book scanning contractors for the Internet Archive,8 has started buying books in quantity.
Innodata just hired a senior book buyer for its new AI data program. “This is a builder role requiring entrepreneurial thinking and operational execution,” the job posting said. Among the requirements for the position was “familiarity with used-book marketplaces” including AbeBooks. Like the other AI book intermediaries, Innodata expects to buy a lot of books. The newly hired buyer will be required to “design and optimize warehousing and fulfillment operations to handle large-scale book inventory across multiple locations.”
Scanning Companies
Once an AI company acquires printed books for training purposes, they need to be scanned. At least two companies, and probably more, are providing this service.
Datamation Imaging Services
Anthropic selected Datamation Imaging Services, located in a Chicago suburb, to scan books for Project Panama. A contract released as an exhibit in the Bartz lawsuit called for Datamation to scan between 500,000 and 2 million books.
If that seems like a lot, it’s not, despite the heaps of media attention given to Anthropic’s scanning program.
ARC Document Solutions
As far as I can tell, no news outlet has reported on ARC Document Solutions, which is scanning as many books every month as Anthropic’s Project Panama envisioned scanning in its entirety.
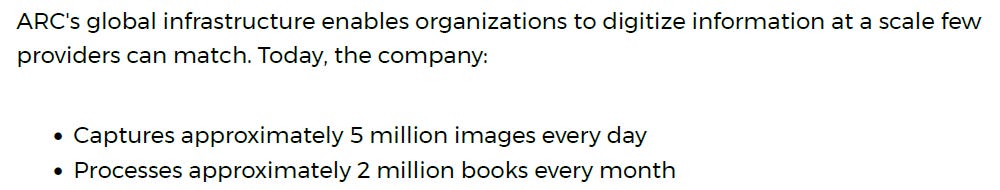
ARC’s current rate of scanning of 2 million books per month is up from the 1.5 million books claimed on a trade show banner six weeks ago, at the beginning of July.
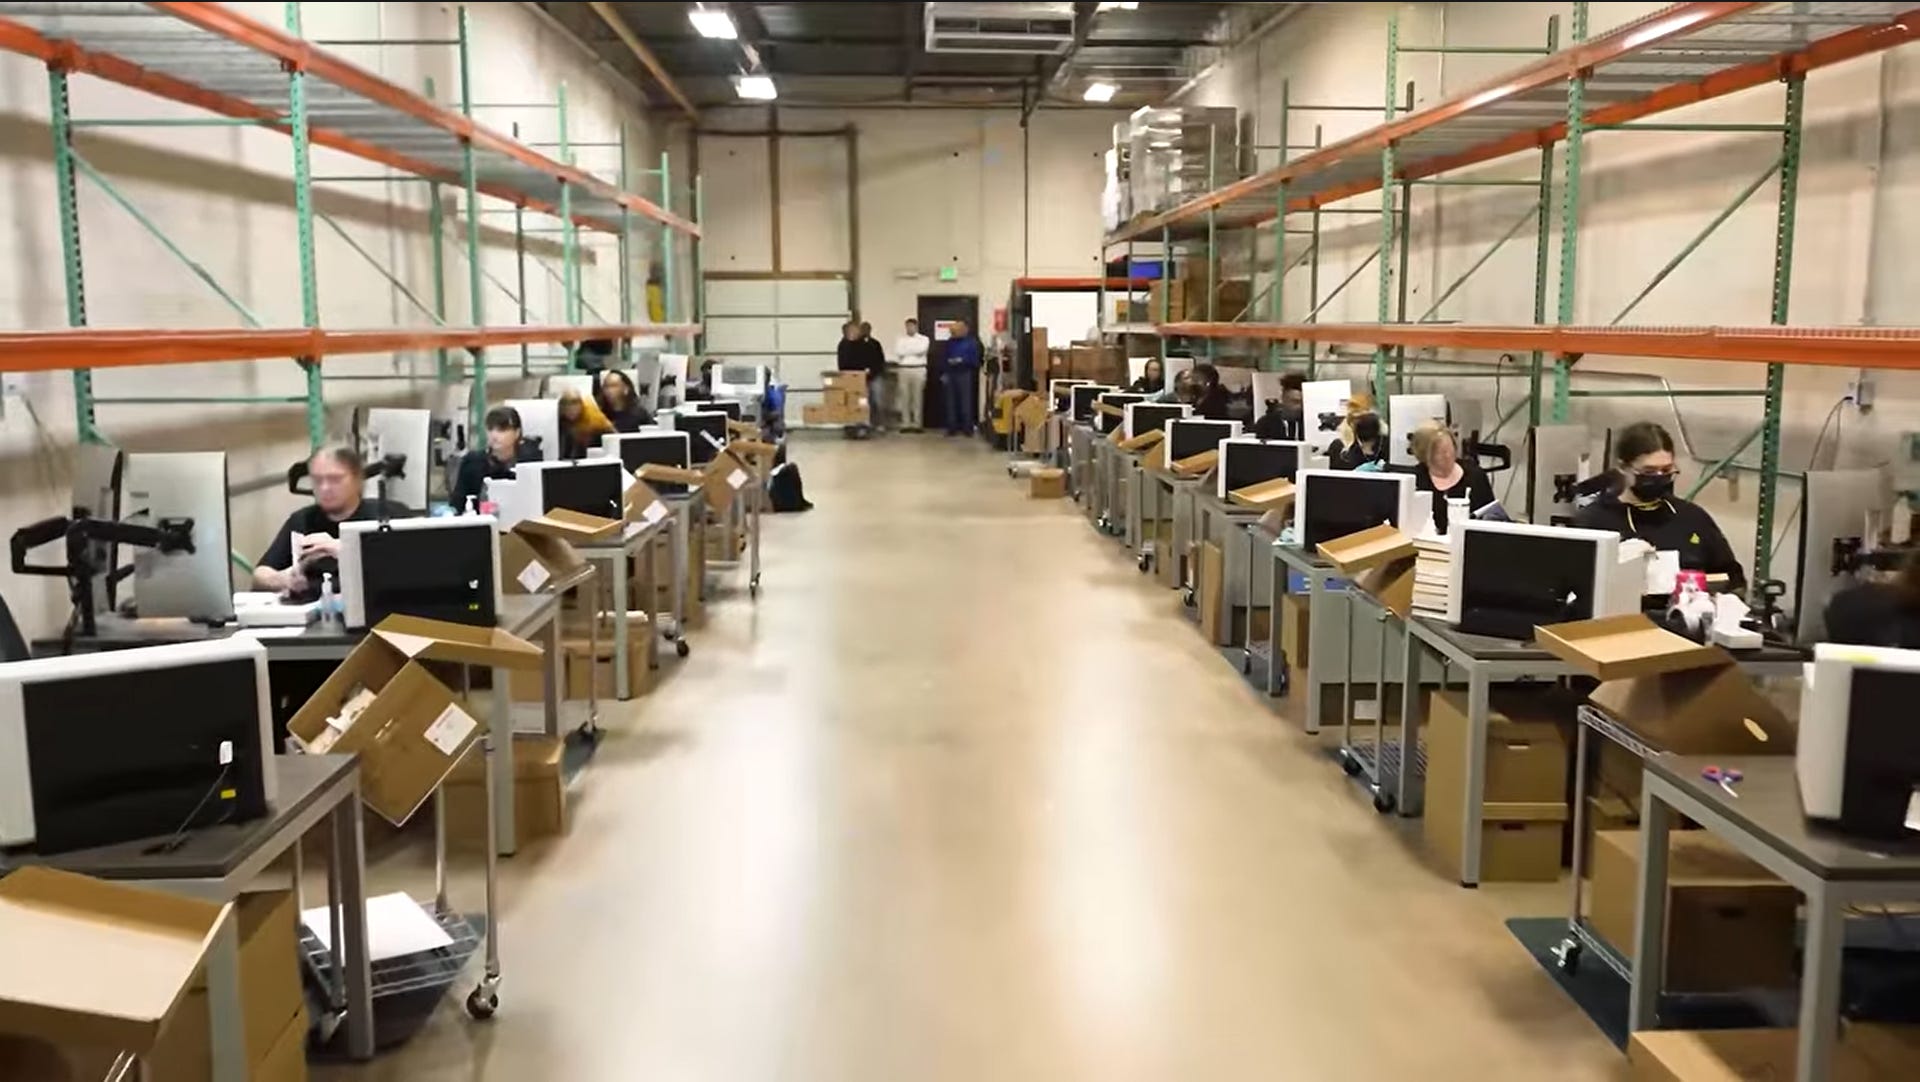
In a promotional video, an ARC executive says that many of the company’s scanning locations “run twenty-four hours a day, three shifts, including weekends,” adding, “It’s very exciting for us.”
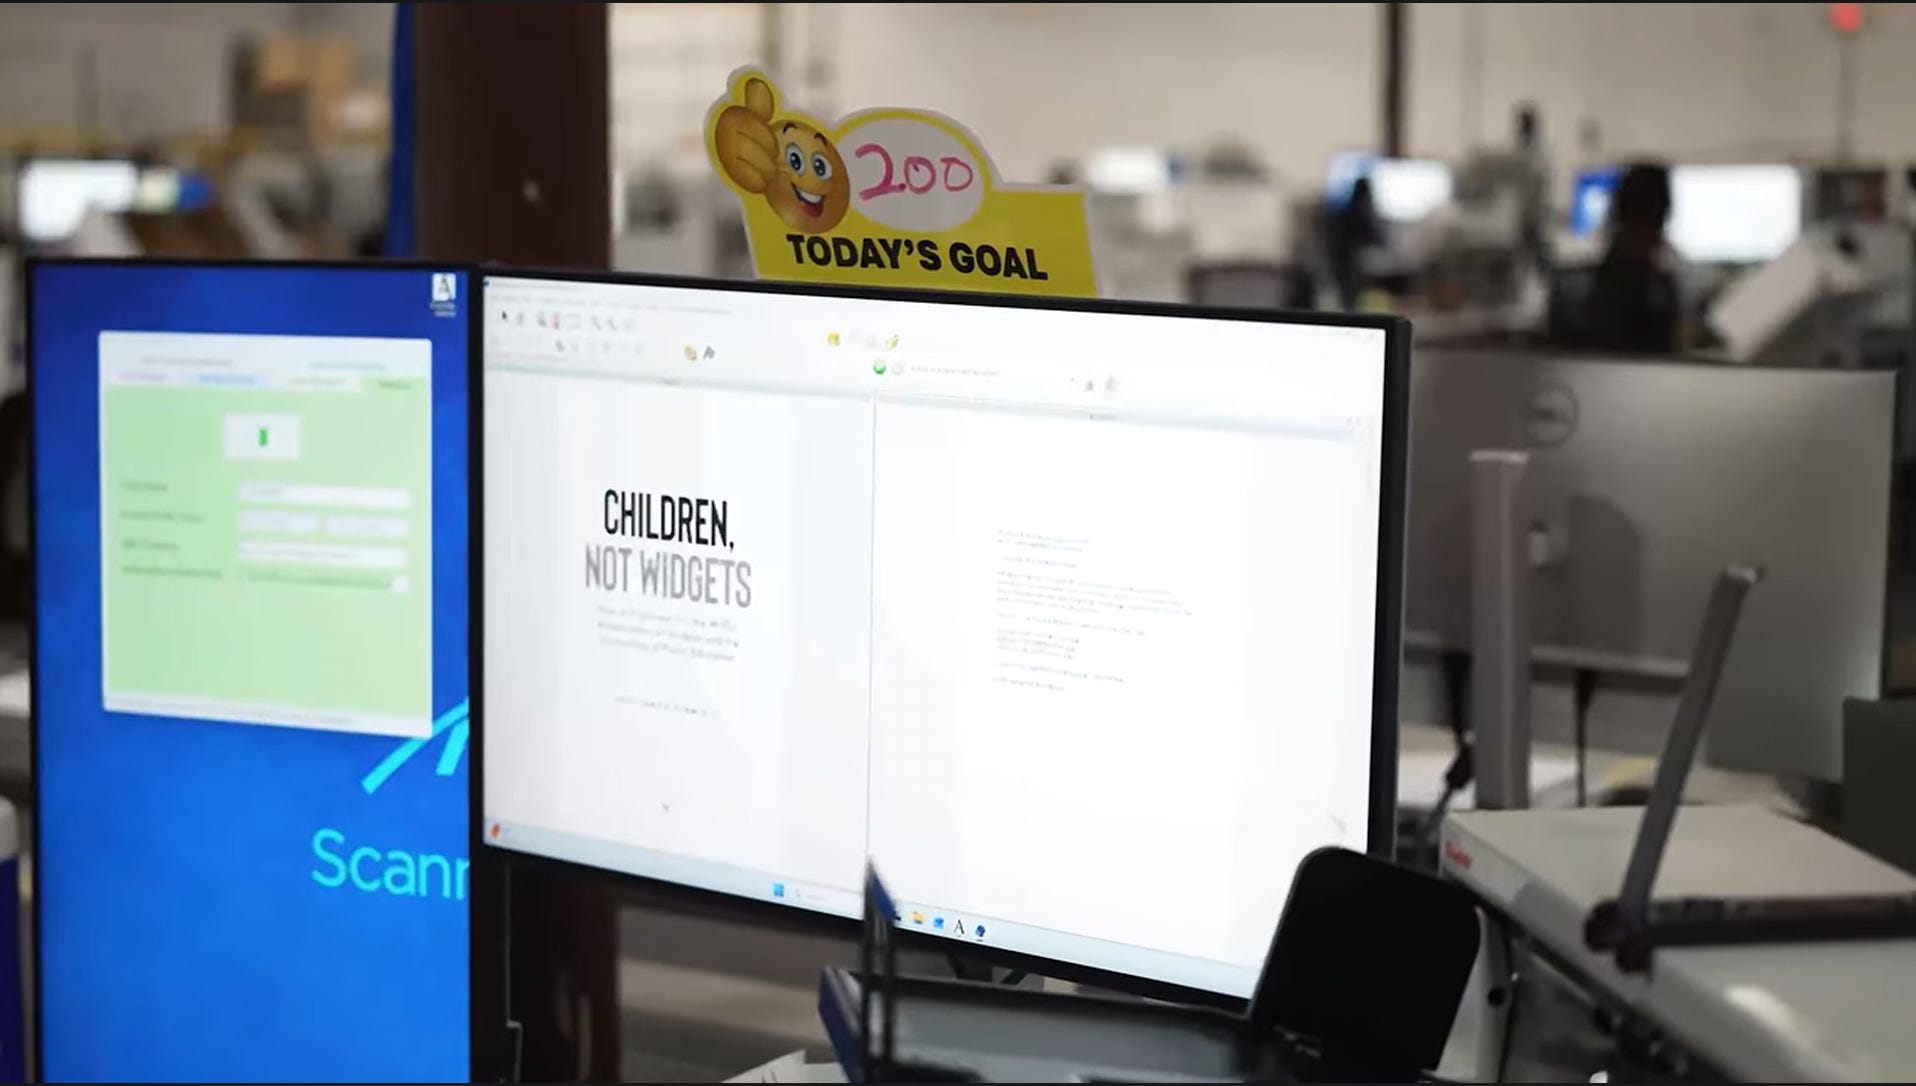
A sign above a monitor at one of their scanning facilities appears to set a production goal of 200 books per day. For a roomful of scanners, that would be about 3,000 books per shift. In a year, one group of scanners working seven days a week can process more than two million books.
Suddenly, ARC’s two-million-books-per-month claim doesn’t seem so far fetched. Do the math. That’s 20+ million books per year, and we are in the second or third year of AI book scanning. ARC is just one company. The total number of books destructively scanned to feed AI could easily be more than 50 million.
Just two weeks ago, a story on book scanning was headlined, “Someone Is Mysteriously Snapping Up Used Books.” That already seems quaint. It’s more like “Every Serious AI Company Is Buying All the Books It Can Find.”
At least the robots are absorbing the contents of the books, so the books that get destroyed live on? Nope, that’s not how large language models work.
Not long ago on Facebook, Michael Winne, a bookseller for the last forty-one years, posted about the many orders he had received that he thinks are destined for AI companies. One day, he sold 110 books for more than $10,000, or nearly $100 per book.
He explained why he was not concerned about sending books to be digitized for chatbots. “When AI trains with books,” he wrote, “the contents of those books eventually become readily available to everyone.”
Large language models behind free chatbots don’t work that way. They don’t remember the books they’ve read.
In fact, the easiest way to think about how AI products use books is to put it in human terms. The foundation of the commercial offerings of AI companies are large language models, massive statistical datasets mapping connections between words. In human terms, LLMs are memory and cognitive skills like reading and basic problem-solving.
An early step in the development of LLMs is text pre-training. As with humans, LLMs start out by “reading” short texts. From these short texts they learn about language, people, and the physical world. Most pre-training materials come from the public Internet, meaning that AI’s first glimpse of humanity originates on Reddit and corporate websites.
Books serve as an important corrective, teaching LLMs about well-reasoned arguments and the careful construction of prose writing. Books punch well above their weight in the models. As a Meta engineer put it, “the best resource we can think of are definitely books.” Authors, editors, and proofreaders refine the text in books before they are published, and books include information not found online, as everyone who starts a research project on Google and ends up consulting a printed work knows.
Even though AI companies are destructively scanning tens of millions of printed books, compared to the trillion web pages on the Internet, books make up a very small part of the typical pre-training dataset. AI2, a nonprofit research center funded by Paul Allen, a co-founder of Microsoft, devotes just 0.2% of its pre-training data to books.9
Books are also important during the “context extension” phase of LLM development. This is when AI companies teach their models to ingest and reproduce long text passages. Books tell coherent stories and make extended arguments that are not generally found online.
Just as with humans, LLMs do not build databases of facts as they “read” books. Human readers remember a few details, but we can’t say what’s on page 163 from memory. Neither can LLMs. That’s why commercial chatbots, despite having read almost everything, still search the Internet to answer most questions. Like humans, LLMs half-remember a lot of their reading.
Sending a scarce title to an AI company for destructive scanning doesn’t preserve the book or the information. It’s not so different from selling a book to a person who reads it and throws it away. The impression of the book remains, but only the impression.
There’s no guarantee that regular people will ever encounter a particular AI model’s impression of a book used in its training. The only guarantee is that the book is gone. Some AI projects never make it into production, and others are turned into customer service chatbots.
AI companies don’t buy rare and collectible books? Nope, they’ve ordered some from me.
Just five hours after my Substack on book scanning went live, an AI front company ordered a rare-ish book from me: a copy of Futuria Fantasia, a 2007 reprint of the science fiction magazine Ray Bradbury published as a teenager. This copy meant a lot to me personally. It belonged to Tom Garner, one of my first customers, whose collection I acquired after he passed away.
The booksellers Patti and Craig Graham printed about 1350 copies, and it’s not especially scarce. I priced mine at $90.

Rather than rare, my copy of the book was collectible. Bradbury, approaching ninety years old, inscribed it to Tom.
The dealer Rebecca Romney says, “We read for the story in the book; we collect for the story of the book.” Tom is part of the story of this book. LLMs can only ingest the story in the book. An AI company would cut off the spine of Tom’s book to capture its textual value. I couldn’t ignore the irony that Bradbury is known for writing a novel about a society that destroys its books, although in Fahrenheit 451 books are burned, not shredded. If Tom were around to ask, I am confident that he would not want his book sent to the guillotine.
The AI company likely tried purchasing my Futuria Fantasia because it was the cheapest listing with an ISBN. Other dealers offered less expensive unsigned copies, but they hadn’t included the ISBN, and the purchasing software apparently couldn’t find them. The next cheapest copy with an ISBN was also signed.
Cancelling my order, I thought, would serve little purpose. Tom’s book would be saved; some other collector’s former copy would be sacrificed along with Bradbury’s autograph.
To remove any uncertainty that the book was destined for AI, the order included an instruction to put the word SCAN in all caps on the first line of the address label. AI companies may be secretive but they aren’t subtle.
I decided to save Tom’s book from the chopping block by arranging for an unsigned replacement to be sent instead, a process called drop shipping. Lawrence Person, of Lame Excuse Books, refused my request to substitute his copy for mine. “I don’t mind drop shipping,” he wrote me. “I do mind sending a book like this off to be destroyed.” He also sent me a link to his blog post critical of AI.
I found another bookseller who was game to send his Futuria Fantasia to eventual recycling. He appreciated my desire to save an inscribed copy and told me he had a signed copy of the book in his personal collection.
Many booksellers I talked to about AI purchases agree that some books should not be sent for destructive scanning. In my previous post, I wrote about a collectible children’s book I did send to be scanned. The dilemma is knowing where to draw the line, and that’s an issue the book trade has never had to face before.
It was rather a lot of human effort to save one copy of Futuria Fantasia from destructive scanning. Three experienced booksellers weighed the value of various copies and found a solution in the best interest of the books and AI. When we were done, I deleted the ISBN from my description of Tom’s copy in the hope that another AI company won’t try to order it.
Only one copy of each book gets destroyed, so we aren’t losing anything? Nope, thousands of titles are disappearing from the marketplace.
There are thousands of book titles that are plentiful enough to turn up regularly in thrift stores and used book shops. Although their authors might object to those books being reduced to AI fodder, few book lovers see their destruction as a great loss.
But there are also a lot of books with fewer than ten copies available for purchase online. The Internet gave the book trade, collectors, and readers an illusion of abundance. A title with listings for ten copies seems common, where forty years ago a book that could be found in just ten shops worldwide would have been very hard to find.
If Anthropic was the only company buying books, this would not matter. Anthropic may have been first, but it is not alone. There’s Meta, and SpaceXAI, and all the customers of Zoom Books, Far Corner, Last Token, and Innodata, plus all the other businesses that have not attracted public attention. And they all want more or less the same books. AI purchasing agents backed by virtually limitless budgets can turn seemingly common books into scarce or even unobtainable ones in very short order.
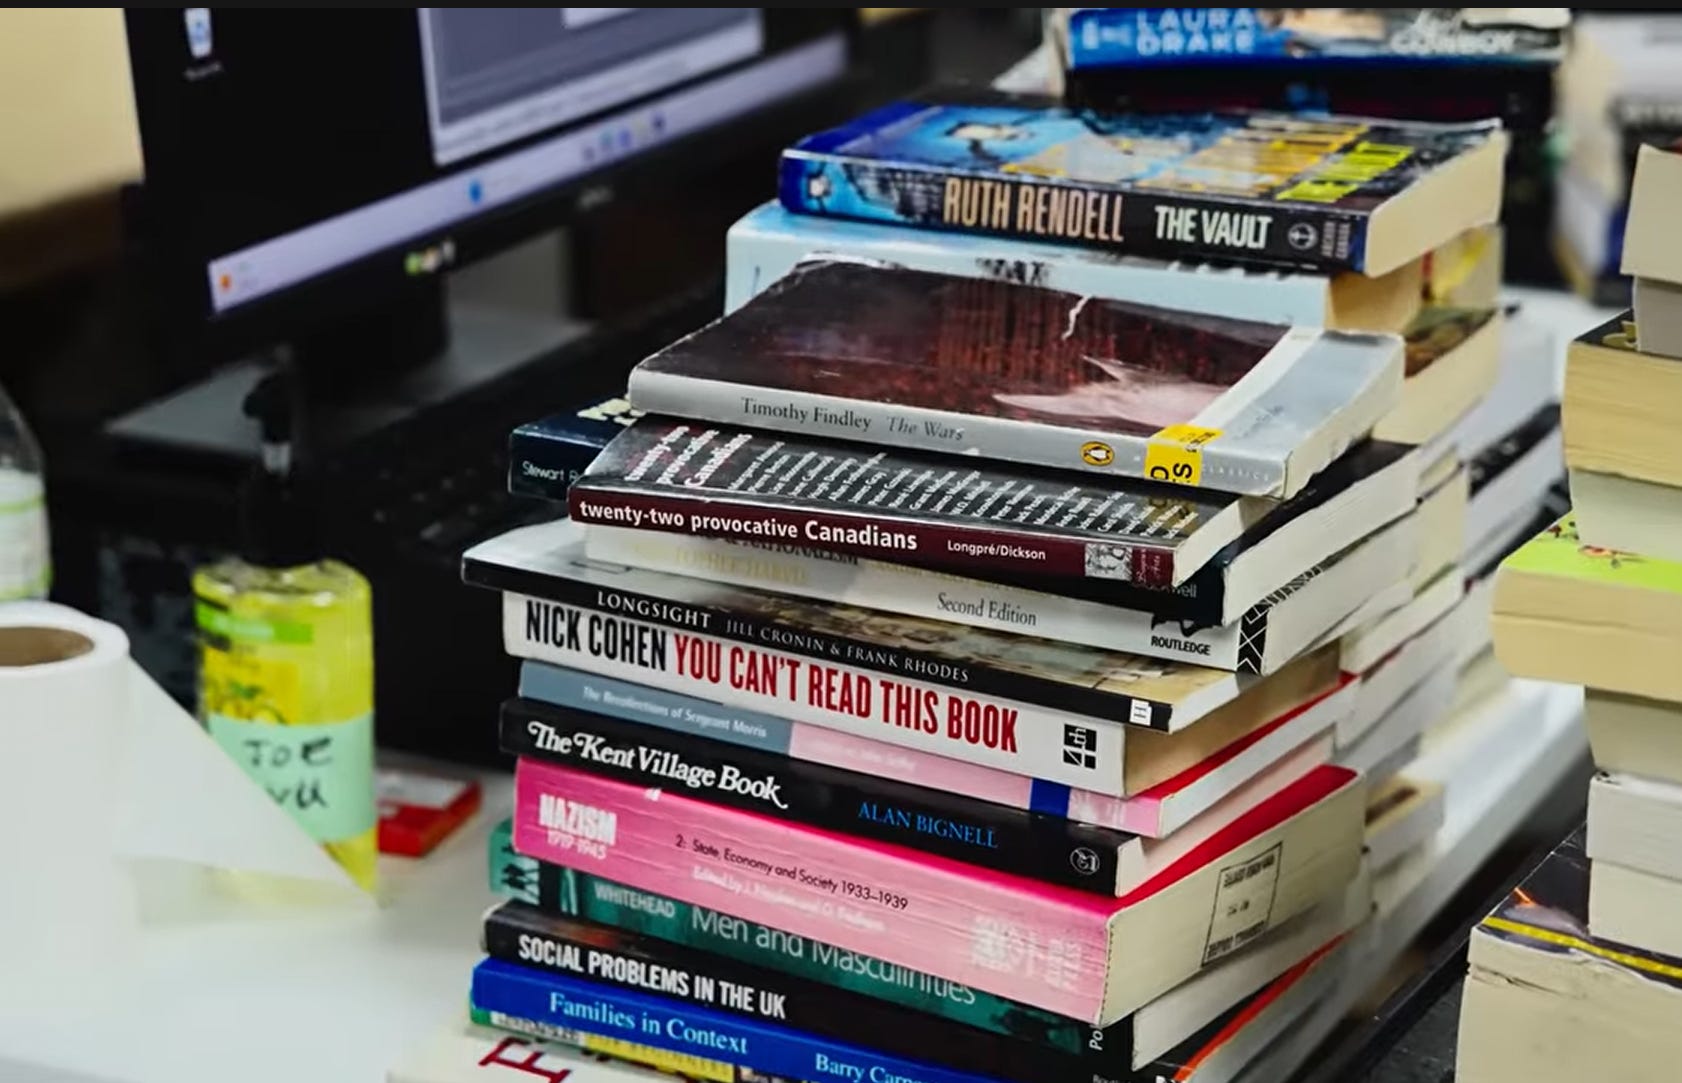
A stack of books awaiting destructive scanning at ARC Document Solutions makes the point. Some of the books are very common, like genre fiction from Ruth Rendell and Laura Drake. Nick Cohen’s look at censorship, You Can’t Read This Book, has a title that will be literally true for that copy once the spine is cut off, but other copies are not hard to find. Twenty-two Provocative Canadians, however, is out of print and ViaLibri.net locates five copies (not counting one that appears to be a bookjacker). It would not be surprising if all five copies were absorbed by AI purchasing agents in the next year. Longsight is another book with fewer than ten copies currently on the market.
If even a small percentage of the tens of millions of books purchased so far by AI companies were available in a handful of copies, then tens of thousands of thousands of titles are no longer available to readers and collectors.
More than rare books, it is these uncommon titles, that bother me. Two of the five books I sold to AI companies were unique on the market, as were two of the books sold by Lucy Kruesel. Several months later, no additional copies have surfaced.
These books exist in libraries, but ordinary humans won’t be able to own them, spend months reading them without worrying about late fees, or have them on the shelf to consult when the need or simple curiosity arises. A handful of AI companies intent on destructive scanning have deprived all 8 billion humans of the opportunity to acquire these books for some unknown period of time.
These AI guys can’t be as bad as everyone thinks they are? Nope, AI industry executives are astonishingly cavalier about their book-destroying practices.
The AI boom is creating vast wealth and a no-holds-barred struggle for dominance in a business where books are seen as especially valuable assets. Authors are pissed that AI companies used pirated ebooks to train their models. The alternative, destructive scanning, is equally unpalatable.
The destruction of books, whether by banning or burning, is seen as an assault on culture. Even the most odious example, the book burnings in Nazi Germany, didn’t materially diminish the number of books in circulation. The Holocaust Encyclopedia says, “students threw tens of thousands of books into bonfires” (emphasis added). The goal was symbolic.10
AI companies aren’t destroying tens of thousands of books, they are destroying tens of millions of books.
This process is symbolic, too. The richest, most powerful people in the world are capitalizing on the work of writers without compensation and in the worst ways, using pirated ebooks and sending physical books to be guillotined.
The callousness of the AI companies is apparent in the way they talk about the process, like Anthropic’s goal to “destructively scan every book in the world.”
Innodata, perhaps the creepiest of the AI-centric companies, alerts us to the fact that our whole lives are up for sale to train the robots. In addition to its brand new book-scanning service, the company’s existing line of AI training datasets includes bank statements, utility bills, customer service calls, receipts, invoices, and selfies.

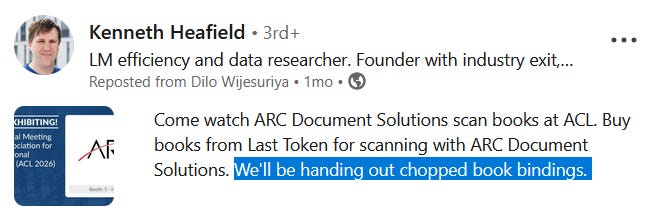
The founder of Last Token, the recently launched book-data-for-AI company, announced that he would be attending a conference and could be found at the ARC scanning booth.
“We’ll be handing out chopped book bindings,” Heafield said, treating the remnants of destructively scanned books as party favors.
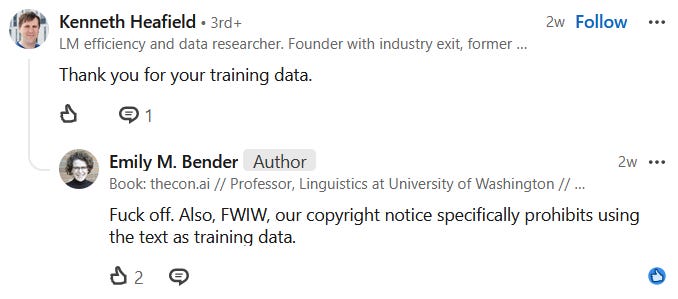
Heafield also trolled Emily Bender, one of the leading academic critics of AI, when she posted on LinkedIn about her book, The AI Con. Heafield commented, “Thank you for the training data,” reminding Bender that her years of work would soon be converted to probabilities in an AI chatbot.
This tone-deafness to the widespread public distaste for the rapaciousness of AI companies extends to the businesses doing the destructive scanning.
Check out this video ARC posted of destructive scanning set to jaunty music.11
AI CEOs preach a vision of a wonderful AI-driven future for humanity. The first issue of Ray Bradbury’s magazine, Futuria Fantasia, also offers a plan for a Utopian future. It could have come from almost any believer in artificial intelligence, if “AI” is inserted as the first word.
AI is not a political or revolutionary movement. It is 100% American. It cannot work anywhere but on the American continent, because only here have we the necessary technological developments, the necessary trained force of technicians, and the necessary resources to institute an economy of abundance in place of an economy of scarcity.
The road to AI abundance, it turns out, is littered with the chopped bindings and scattered pages of tens of millions of books.
—Scott Brown, Downtown Brown Books
A note on sources: Ken Heafield, Last Token, Emily Bender, and Meta did not respond to my requests for comment. ARC’s comments to me focused on non-destructive scanning, which is great, and their robot to do it is pretty cool. AI companies, however, are almost exclusively choosing destructive scanning for legal and cost reasons. My evidence is cited in the hyperlinks; where possible I ensured the details have been captured by the Way Back Machine. I don’t have a Facebook account, so I did not link to the specific posts I referenced. I did save screenshots, however.
Credit goes to Adam McInturf for reminding me about The Dude.
See footnote 4.
Calculated by comparing the World of Books Group Ltd. EBIDTA numbers for 2023 and 2025. As a British corporation, the company is required to file annual financial statements with the Companies House.
A bookseller shared a Zoom Books email with me: “I’m Manroop Gill, co-founder of Zoom Books—the largest book processor in Canada. We run two facilities and process around 200,000 books a day for institutional, academic, and library customers across North America. We’ve been buying books from [you] through online marketplaces, and I’d love to work with you directly…. We pay a 50% deposit up front, before we ever ask you to delist anything. Once your order is picked, packed, and ready to ship, we send the remaining 50%—nothing leaves your warehouse without full payment. To get started, all we need is your inventory list (ISBN, price, and stock confirmation)… We run it on our end and send you back an order.”
Zoom Books had a post on their blog about using books for AI training. The Way Back Machine captured a link to the post but not the content. The article is no longer online.
Snapshots of SuperBookDeals.com on the Way Back Machine suggest the website was working until a few weeks ago.
The source of this information is confidential, but reliable.
The Internet Archive shipped containers full of books, LPs, and other analog media to Innodata’s scanning facility in Cebu province in the Philippines. Innodata employed non-destructive methods to digitize the media, much of which was borrowed from libraries and returned. The book records on the Internet Archive website identify the location of the scanning and sometimes the person doing the work. It’s not clear if Innodata will scan for AI in the Philippines, too.
Some models may obtain more than 0.2% of training data from books, however the percentage likely tops out in the single digits. The 0.2% number was calculated from the pre-training sources for AI2’s Dolma, which totaled 2.7 trillion tokens (a data measure used in AI), of which 5.2 billion were books.
It seems ridiculous to even have to say this but I am not comparing AI companies to Nazi.
The first part of the video shows their non-destructive scanning program. ARC’s VP of Marketing, David Villarina, told me “Our focus area is on digitizing large organizations’ proprietary physical knowledge, which often is in the form of paper, to be used with their own AI instances. Although we have done a significant amount of book scanning, the opportunity we are pursuing is on capturing this proprietary information, unique to each company, for AI training data.”
Pulitzer caliber posting
As a fellow book lovers, this broke my heart. I once got to hold precious ancients books at the University of Nottingham’s library with the oldest being from the 1700s. I couldn’t believe it even existed. I can’t imagine doing any physical harm Like this.
(Ps, restacked for reach and now a new follower. P.p.s. The Dude is right to be incensed!)